Evals for AI agents & LLMs
Expert-labeled golden sets, scoring rubrics, side-by-side model and prompt comparisons, failure taxonomies, and regression suites that run before every model, prompt or retrieval change.
Product leader across AI, consumer and B2B products. 7+ years turning uncertain bets into measurable businesses and shipped products.
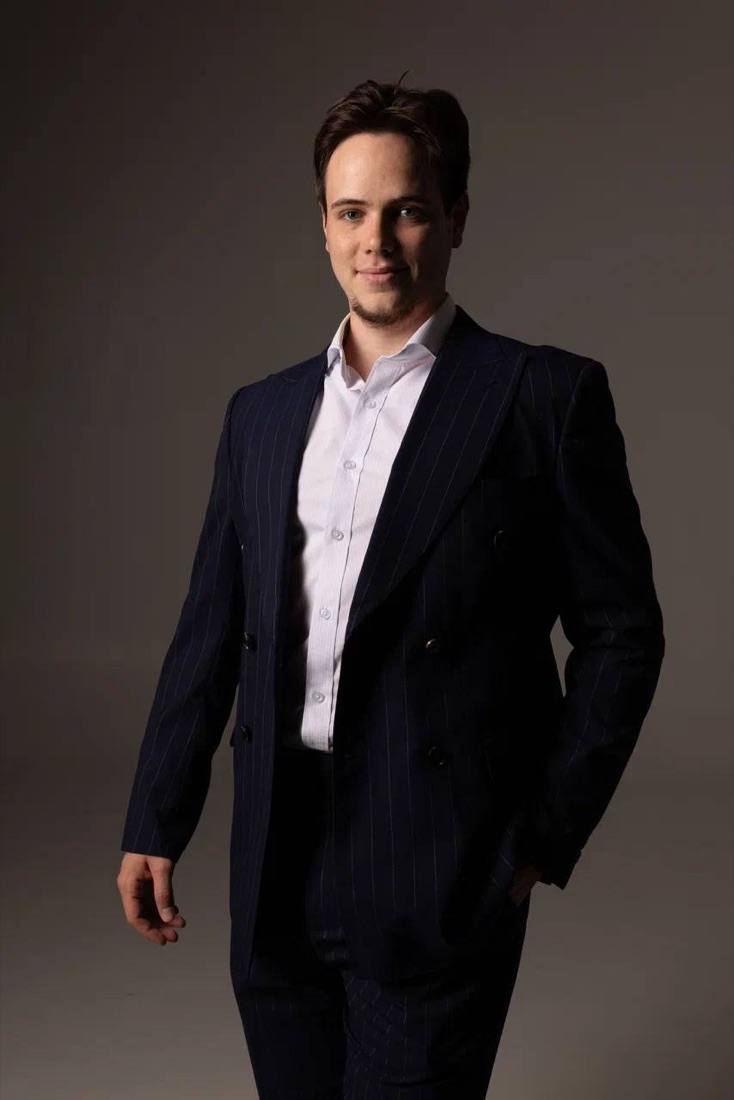
Senior product leadership where the problem is consequential, the path is still unclear, and shipping matters.
Strategy, operating cadence, team alignment and executive decision support.
Evaluation systems for AI agents and LLMs: SME benchmarks, golden sets and scoring rubrics, safeguards against unsafe or off-policy output, and release gates that keep quality measured after launch. How it works
Use-case selection, product design, evaluation and implementation inside real company workflows.
Segmentation, experimentation, pricing and the systems needed to learn faster.
Evidence-led diagnosis followed by a practical roadmap and hands-on delivery leadership.
Core competence: the evaluation systems that decide whether an AI agent or LLM feature is accurate, safe and worth running inside a real workflow.
Expert-labeled golden sets, scoring rubrics, side-by-side model and prompt comparisons, failure taxonomies, and regression suites that run before every model, prompt or retrieval change.
Adversarial and edge-case testing for hallucination, off-policy or unsafe output and data leakage, with guardrails and human escalation designed into the product rather than bolted on.
Whether an agent actually finishes the real workflow: task completion, human handoff rate, cost of errors, and latency and spend per completed task, measured against the manual baseline.
In the record: AI Stat, every agent task scored against SME benchmarks and stress-tested on ~8,500 Agricultural Census questions before production; Lawrify at Yandex, a legal AI agent with an eval stack built end to end: expert-labeled golden sets, scoring rubrics, side-by-side model and prompt comparisons and a failure taxonomy; Lovel, evals across chat AI pipelines and image generation.
First-hand accounts from founders who worked with Nikita through pivotal product moments.
“Nikita introduced a disciplined product process where hypotheses were systematically tested, experiments were translated into measurable outcomes, and the team began shipping with consistent weekly cadence.”
“He combines strategic thinking with empathy, leadership with collaboration. He quickly earned the trust of both executives and team members, creating an atmosphere of ownership and accountability.”
“Mr. Simakov played a central role in shaping our product and growth strategy… transforming raw ideas into a coherent product roadmap.”